

Introduction
One of the most common criticisms of student AI use today is that students are no longer thinking for themselves. Some debate coaches share this worry, fearing that debaters outsource reasoning, recycle machine-generated arguments, and lose the capacity for “original” thought. If an AI helped write the case (or a coach, though coaches complain about that less:)), the thinking must not be real.
This criticism reveals a fundamental misunderstanding of how knowledge develops—not just in debate, but across every field of human intellectual achievement. Ideas have never emerged in a vacuum. Debate has always functioned as a distributed cognitive system where thousands of minds contribute to a shared reservoir of arguments that improve through competition, feedback, and iteration.
The debate community is not thousands of isolated thinkers. It is one giant brain.
What AI and other technologies change is not the fundamental nature of how debate produces knowledge—it’s the speed at which ideas circulate and the accessibility of that shared knowledge base. The underlying process remains identical: collaborative ideation, public testing, iterative refinement, and accelerated learning through iteration.
Understanding debate as collective intelligence reveals why fixating on individual originality and many current instructional approaches misses what actually matters: whether students learn to think critically, evaluate evidence, construct arguments, and adapt under pressure. Debate has always trained these capacities through a process that looks nothing like solitary genius and everything like a rapidly evolving intellectual ecosystem. If we want students to “be prepared for the future,” (really the present) they all need to start learning this way.
Where Ideas Actually Come From
History undermines the myth of solitary originality at every turn.
Albert Einstein did not generate relativity from nothing. His ideas emerged from centuries of physics, mathematical traditions developed by others, correspondence with contemporaries, and thought experiments that borrowed and extended existing concepts. Einstein built directly on Lorentz transformations, which were already circulating among physicists trying to reconcile electromagnetic theory with mechanics. He corresponded extensively with Michele Besso, who helped him think through the problem of simultaneity. He drew on Ernst Mach’s philosophical critiques of absolute space and time. His thought experiments about trains, clocks, and light beams extended examples that other physicists had already used to explore relativity problems. His breakthroughs were revolutionary, but they were intelligible only within a shared intellectual framework built by generations of scientists. Even Einstein’s genius was collaborative.
Joseph Nye’s concept of soft power (Soft Power: The Means to Success in World Politics),, which reshaped how we understand international relations, followed the same pattern. Nye was building on decades of work in international relations theory—realism from Morgenthau (Power Among Nations) and Waltz (Realism and International Politics), liberalism from Keohane (Power and Interdependence), constructivism from Wendt (Constructivism and IR: Alexander Wendt and His Critics). He was responding to specific policy debates about American decline in the 1980s, when scholars worried that Japan’s economic rise meant the end of American dominance. He synthesized observations from Cold War cultural diplomacy, the appeal of American movies and music abroad, the influence of American universities, and the attractiveness of democratic values. The idea was novel and influential, but it was not disconnected from the intellectual ecosystem that produced it. Nye synthesized, recombined, and extended what others had already thought.
Even everyday radical innovations follow this logic. As AI researcher Ben Goertzel has noted, entirely new genres like fusion rock feel unprecedented when they emerge. But consider how fusion rock actually developed: Miles Davis brought jazz harmonies to rock instrumentation after listening to Jimi Hendrix and Sly Stone. The Mahavishnu Orchestra combined Indian classical music’s rhythmic complexity with jazz improvisation and rock’s electric intensity. Weather Report blended Afro-Cuban percussion with electronic keyboards and jazz composition. Each artist was trained in existing traditions—jazz, rock, classical, world music—and innovation came from intentional collision and recombination. The novelty was real, but it depended entirely on shared material.
This pattern reflects what economist Martin Weitzman identified as “recombinant growth”—new ideas emerge from combining existing ideas. Given n ideas, the number of possible innovations equals n(n-1)/2. Innovation is initially constrained by available components, but possibilities grow explosively once sufficient building blocks exist.
Think less “lightning bolt” and more “Lego set.”
If you only have a few Lego pieces, there aren’t many things you can build. But as the number of pieces grows, the number of possible combinations grows much faster than the number of pieces themselves.
That’s what the little bit of math is trying to show.
If you have n distinct ideas, the number of unique pairings you can make is n(n–1)/2. So:
5 ideas → 10 possible pairings
10 ideas → 45 pairings
100 ideas → 4,950 pairings
The key point isn’t the formula. It’s the curve. Each new idea doesn’t just add one more option. It multiplies the space of what’s possible.
Early on, innovation is slow because there just aren’t enough building blocks. Progress feels incremental. But once a field accumulates a critical mass of ideas, tools, and concepts, innovation can accelerate dramatically. Suddenly, people can recombine things that were never meant to go together.
That’s why breakthroughs often cluster in time. They look mysterious in hindsight, but structurally they’re predictable once the ingredients exist.
Scientific progress works this way. Artistic movements work this way. Policy development works this way. And debate works this way, with unusual speed and transparency.
The question is not whether students are building on shared knowledge. They always have been, and they always will be. The question is whether the system they are operating within rewards genuine understanding, critical evaluation, strategic thinking, and adaptation—or whether it allows superficial engagement to masquerade as learning.
Debate’s structure ensures the former. That is what makes it a powerful educational tool, with or without AI.
How Debate Actually Works: Public Forum as a Case Study
To see how debate functions as a collective cognitive system, consider Public Forum debate, one of the largest and most accessible competitive formats.
[Notes —
(1) In March I will look at Lincoln-Douglas debate and in May I will look at Policy Debate
(2)] My reference to the “case list” throughout is the set off all arguments that students made on the topic that they have publicly disclosed. I’ve consolidated over 2,000 pages of it here. It is both over and under-inclusive. It’s over-inclusive because you’ll undoubtedly find some redundancy; I didn’t have the time to clean out every duplicate. It’s under-inclusive both because I don’t think I found every argument and because some teams choose not to disclose their arguments. These limits in tow, I think it’s a good comprehensive look at what students spent two months (November-December) debating about. I intentionally didn’t list the arguments by team so as not to more broadly disclose all the students’ identities. ]
___
Each fall, thousands of students across the country debate two topics.
One resolution runs from September to October and is announced early enough that preparation begins in the summer.
The second runs from November to December and is announced on October 1, giving teams roughly thirty days to prepare. Preparation never truly stops. Students begin thinking about the next topic (November-December) while still competing on the current one (September-October), carrying forward arguments, evidence, analytical frameworks, and strategic insights.
Ideation & Research
The cycle begins with ideation. Students brainstorm based on their existing knowledge [EK]
Then students do initial readings, videos they watch online, news coverage, current events, and arguments they have encountered in past debates. They begin reading and find new arguments and new ideas that are unique to the topic, doing their own secondary source research [SSR]
{EK + SSR}.
Using Foundational Knowledge [FK]
Topics change, but core issues often recur. Climate change, economic stability, national security, human rights, technological regulation—these themes surface again and again in different contexts. Arguments migrate across resolutions.
Take a concrete example: human trafficking arguments and how they are debated under three resolutions.
September-October 2024
Resolved: The United States federal government should substantially expand its surveillance infrastructure along its southern border.
September-October 2025
Resolved: The United Kingdom should rejoin the European Union.
November-December 2025
Resolved: The United States federal government should require technology companies to provide lawful access to encrypted communications.
When students debated about border surveillance in 2024, teams developed arguments about how increased surveillance could help detect and disrupt transnational human trafficking networks along the U.S.-Mexico border and enhance cross-border law enforcement cooperation. Those same analytical frameworks reappeared a year later in the topic about the UK and the EU, where debaters argued about human trafficking networks operating across EU member-state borders and how Brexit weakened UK-EU law enforcement cooperation against trafficking.
Then, on the encryption topic, teams adapted the logic once more. They argued that requiring lawful access to encrypted communications would give law enforcement critical tools to break open encrypted messaging systems that human traffickers use to coordinate operations, recruit victims, and evade detection, pointing to law enforcement statements that inability to access encrypted devices can leave victims of human trafficking and child exploitation without justice.
{EK + SSR +FK}
Initial Community Knowledge [ICK]
There is a significant amount of initial community knowledge that students also draw on.
First, there is community knowledge from collective argument case lists that I’ll talk about later.
Second, there are relatively inexpensive resources that can be purchased to support initial arguments.
They use brief companies like Champion Briefs and DebateUS (full disclosure: I own DebateUS) that compile evidence, outline arguments, and provide analytical starting points.
For example, on the November-December 2017 topic “The United States should require universal background checks for all gun sales and transfers of ownership,” brief companies provided:
Evidence from peer-reviewed criminology journals on firearm mortality rates
Constitutional law analysis from legal scholars on Second Amendment jurisprudence
Public health data from the CDC and state health departments on gun violence trends
International comparisons from countries with different firearm regulations
Argument outlines showing the logical structure of cases for and against the resolution
Third, students pull from back files—archived cases and evidence from previous years.
{EK + SSR +FK + ICK}.
Coach Knowledge (CK)
Debate coaches sit on a pretty unusual kind of knowledge. It’s not just academic expertise and it’s not just intuition. It’s pattern recognition built up over hundreds or thousands of rounds, topics, and seasons.
First, coaches know what actually wins debates. After watching the same resolution argued again and again across tournaments, they see which arguments survive crossfire, which collapse under basic questioning, and which consistently persuade judges. Over time, weak claims disappear and strong ones get refined. Coaches remember, sometimes very precisely, “This argument sounds good on paper, but it always dies once someone presses the internal link,” or “Judges reliably buy this impact framing if it’s explained clearly.” That kind of knowledge rarely shows up in articles or briefs, but it’s incredibly predictive.
Second, coaches understand how arguments develop over a season. Early tournaments are messy. Arguments are undercut, evidence is thin, and framing is crude. As weeks go on, teams respond to each other. They add nuance, patch holes, improve warrants, and sharpen impacts. Coaches track this evolution. They know which ideas are likely to emerge, which lines of attack will become standard, and which positions are going to mature into top-tier strategies by October or November. That lets them prepare students not just for the first tournament, but for where the meta is going.
Third, coaches have a strong sense of persuasion, not just logic. They know how different judges respond to arguments, how technical a claim can be before it loses accessibility, and how framing often matters more than raw evidence. A coach might tell a student, “This is true, but it doesn’t feel important unless you tie it to fairness,” or “You’re winning the logic, but the story isn’t landing.” That’s rhetorical judgment shaped by constant exposure to real audiences making real decisions.
Fourth, coaches bring their own research into topic preparation in a very strategic way. They don’t just dump articles on students. They filter. They look for evidence that does specific work: clean warrants, comparative claims, and impacts that can be weighed. They also research with an eye toward clash. Coaches ask, “What will the other side say?” and then look for sources that preempt or answer those responses. Their research is shaped by the competitive ecosystem, not just by what is true, but by what will matter in a round.
Finally, all of this gets translated into topic prep as frameworks and guidance. Coaches help students see which arguments are core, which are situational, and how different positions fit together. They explain why some ideas are worth investing prep time in and others aren’t. Instead of students reinventing arguments from scratch, coaches help them adapt proven structures to new evidence and new contexts. That’s how debate knowledge accumulates over time. It’s shared, refined, tested, and passed on.
In that sense, debate coaches function a bit like experienced editors and field researchers rolled into one. They study what works in the real world of argumentation and then use that knowledge, plus their own research, to help students prepare for a topic in ways that are both intellectually serious and strategically sound.
{EK + SSR +FK + ICK + CK}.
From there, teams engage in argument construction. They develop core contentions—major claims supported by evidence and reasoning, as well as rebuttals and frontlines (responses to rebuttals). On the encryption topic, they may have something like this.
Contention 1: Lawful backdoor access is critical for prosecuting human trafficking
The argument begins with the scope of the problem: human trafficking generates $150 billion annually and affects an estimated 27 million victims worldwide, with encrypted messaging apps serving as the primary coordination tool for traffickers. Evidence from Department of Justice reports shows that in 2023, encryption prevented investigators from accessing critical communications in over 400 human trafficking investigations. The impact chain flows logically: when law enforcement cannot access encrypted communications, they cannot identify victims in time-sensitive situations, cannot map trafficking networks to prevent future exploitation, and cannot gather admissible evidence for prosecution even when they know trafficking is occurring.
[Sample Contention]
Contention 2: Lawful access saves government resources and preserves warrant requirements
This argument addresses practical efficiency. Current encrypted investigations require resource-intensive alternatives: extended surveillance operations, informant recruitment, undercover work, and attempts at brute-force decryption. Evidence from FBI budget analyses shows that encryption-related workarounds cost federal law enforcement approximately $800 million annually in personnel time, technical resources, and delayed case resolution. State and local agencies face even starker resource constraints—smaller police departments simply cannot afford the months-long investigations required when encryption blocks direct evidence access.
The efficiency gains are substantial: with lawful backdoor access, a warrant that previously required 6 months of alternative investigation can yield results in days. This means the same investigative resources can handle 10x more cases, directly translating to more crimes solved and more victims protected. Economic analysis shows that faster case resolution also reduces incarceration costs (pretrial detention while building cases without encrypted evidence) and increases deterrent effects (certainty of punishment matters more than severity).
But construction doesn’t stop there. Students prepare rebuttals to each major argument.
A Con team might attack Contention 1 by arguing:
Alternative investigation methods (metadata analysis, financial tracking, physical surveillance) can identify trafficking networks without compromising encryption
International trafficking operations will simply switch to foreign-based encrypted services outside US jurisdiction, making backdoors ineffective
The warrant approval rate (94%) shows warrants aren’t the bottleneck—the real barrier is developing probable cause, which backdoors don’t solve
A Con team attacking Contention 2 might argue:
The $800 million cost is overstated because it includes all encryption-related challenges, not just those solvable by backdoors
Resource efficiency gains assume backdoors work perfectly, but implementation costs (building infrastructure, training personnel, legal challenges) will be massive
Creating backdoors will generate new resource drains: defending against exploitation, responding to breaches, managing increased cybersecurity incidents
Then Pro teams prepare frontlines—responses to those rebuttals:
Against the “alternative methods” rebuttal:
Evidence shows metadata analysis is insufficient for time-sensitive cases where victims are being moved or harmed
Financial tracking requires weeks or months while trafficking victims are suffering daily
Physical surveillance is only possible after identifying suspects, which often requires communication analysis
International services argument is a false dichotomy: most trafficking operations use mainstream apps (WhatsApp, Facebook Messenger) for convenience; even if some sophisticated networks switch services, stopping the majority of trafficking still saves thousands of lives
Against the “cost overstatement” rebuttal:
FBI budget documents specifically isolate encryption-workaround costs from general cybersecurity spending
Implementation costs are one-time investments, efficiency gains compound annually
The “new resource drains” argument assumes backdoors create more costs than they save, but evidence from financial systems shows lawful access infrastructure can be secured with proper investment
A Con case opposing back doors might argue:
Contention 1: Encryption backdoors create systemic cybersecurity vulnerabilities
The argument begins with a technical foundation: any backdoor mechanism accessible to law enforcement is, by definition, a vulnerability that can be discovered and exploited by malicious actors. Evidence from leading cryptographers—including Bruce Schneier and a consortium of cybersecurity experts in a 2015 MIT report—establishes that there is no such thing as a backdoor that only “good guys” can use. The mathematics of encryption are binary: either a system is secure against all unauthorized access, or it contains exploitable weaknesses.
Historical evidence proves this isn’t theoretical. The 2010 Greek phone surveillance system—designed specifically for lawful government intercepts—was compromised by unknown actors who eavesdropped on the Greek Prime Minister and over 100 government officials for nearly a year before discovery. The 2015 Juniper Networks case revealed that backdoors in their enterprise equipment, intended for lawful access, had been exploited by sophisticated attackers (suspected foreign intelligence services) to spy on U.S. government communications. The 2017 Shadow Brokers leak exposed NSA tools designed for lawful surveillance, which were then weaponized into the WannaCry ransomware attack that caused $4 billion in global damages and shut down hospitals across the UK’s National Health Service.
The impact analysis scales from individual harms to systemic risks. At the individual level: compromised medical records, financial theft, identity fraud. At the institutional level: corporate espionage, theft of intellectual property, compromise of attorney-client privilege. At the national level: foreign intelligence services accessing government communications, military systems, critical infrastructure controls.
Contention 2: Insecure networks undermine consumer confidence and damage the digital economy
This argument connects technical security to economic impacts. Consumer trust in digital platforms depends on credible security guarantees. Survey data from Pew Research shows 81% of Americans believe the risks of data collection by companies outweigh the benefits, and 79% are concerned about how companies use their data. Evidence from economic studies of data breaches shows that companies experience average stock price declines of 7.5% following major security incidents, with sustained reputational damage lasting years.
Encryption backdoors would create a trust crisis. If consumers know their communications can be accessed—even with a warrant—they lose confidence in digital services. This isn’t paranoia; it’s rational assessment of risk. Evidence from post-Snowden revelations shows that when users learned about government surveillance capabilities, U.S. cloud computing companies lost an estimated $35 billion in foreign contracts as international clients switched to providers in countries without surveillance requirements.
The economic mechanism operates through multiple channels. First, reduced platform adoption: users who don’t trust security choose alternatives or avoid digital services entirely, shrinking the digital economy. Second, innovation migration: technology companies and startups relocate to jurisdictions without backdoor requirements, as evidenced by WhatsApp and Signal’s decisions to base operations in encryption-friendly countries. Third, competitive disadvantage: U.S. technology companies cannot compete globally if their products have known government access while competitors offer genuine end-to-end encryption.
The scale of potential economic damage is enormous. The digital economy represents approximately $13.6 trillion of U.S. GDP, with technology sector employment exceeding 12 million workers. Evidence from economic modeling suggests that a widespread loss of trust in U.S. technology platforms could reduce GDP by 2-3%, equivalent to a moderate recession, while triggering unemployment increases in the technology sector.
__
That’s just the basics. Let’s look out how debate rounds play out and how a giant intelligence explosion happens inside the debate brain, starting at the first tournament on a topic.
Round 1 (Saturday 8am): The Pro team walks into Round 1 knowing the Con side is likely to run a cybersecurity breach argument about how lawful backdoor access increases cyber security risks. They are ready.
They explain:
Lawful access does not mean a permanent master key.
It means case-by-case access, tied to a warrant, often implemented through endpoint access or key escrow mechanisms that are activated only after judicial approval.
Con’s evidence assumes a single point of failure. That assumption is false.
Pro wins.
The Con is upset they didn’t defeat the Pro’s responses.
After the round, they immediately text their squad’s group chat and post in their team’s Discord. Within 15 minutes, three teammates and two coaches have responded with evidence: one finds a cryptographer’s testimony explaining that NSA tools and commercial backdoors share the same fundamental vulnerability (any access mechanism can be reverse-engineered), another finds historical precedent of the Clipper Chip (a 1990s encryption backdoor proposal) being mathematically broken within months, and a third sends them evidence about how the Shadow Brokers leak specifically happened because the NSA’s backdoor into Cisco routers was discovered and exploited. The pull quotes to support all of this and share it for future rounds.
Round 2 (Saturday 10am):
They are Con and face yet another human trafficking case, but now think they’re prepared. They talked about how backdoors increase surveillance by abusers, how traffickers adapt faster than law enforcement, how encryption protects victims trying to escape. Their rebuttals landed clean.
But the Pro’s second contention was nothing like the first.
This wasn’t about individual crimes. It was about the future. Pro argued that without lawful access, governments could not regulate advanced AI systems. Without regulation, they said, hyper-intelligent AI would spiral out of human control. And if that happened, human extinction was not science fiction but a plausible endpoint. Lawful access was framed as the last lever states had to monitor and contain existential risk.
Con froze.
They had blocks for trafficking. They did not have blocks for extinction.
Their responses were rushed. They tried to say the link was speculative. They said encryption and AI regulation were separate debates. But Pro kept tightening the story. No access means no oversight. No oversight means unchecked AI. Unchecked AI means humans lose the ability to govern their own future.
The round slipped away.
After Con lost, they bolted down the hallway to find their teammates and coaches.Voices overlapped. Someone kept saying, “Why didn’t we think of that?”
Their coach looked exhausted.
“First, the DOJ isn’t some neutral AI sheriff. They don’t even want strong AI regulation. In a lot of cases, they openly oppose it. They aren’t going to enforce any existing regulations. Second, even if regulations existed, hyper-intelligent systems would lie, evade, and route around them. Lawful access doesn’t magically give you control over something smarter than you.”
They work together to come up with a “block of responses.”
In between Round 2 & 3
What happens next is a frenzy of collective learning that has no parallel in traditional education.
Teams and coaches begin systematically mining OpenCaselist, a place where teams post all the arguments they made in previous debates, for three distinct types of intelligence:
(a) Evidence that supports their own arguments
A team running the human trafficking contention discovers that five other teams are also running trafficking arguments, but with different evidence. They find: - A more recent FBI report (2024 instead of their 2023 data) with higher numbers of blocked investigations - A specific case study from Operation Cross Country that provides more compelling victim rescue details - Testimony from a trafficking survivor that adds emotional weight to their impact analysis - Economic analysis quantifying the cost of trafficking in ways they hadn’t considered
They don’t just adopt this evidence wholesale. They evaluate it: Is this source more credible than what we have? Does this data contradict or complement our existing claims? Will judges find this more persuasive? They integrate the best pieces into their case, creating a stronger version than they had after Round 2.
A team on the Con side running cybersecurity arguments discovers: - Technical analysis from cryptographers they hadn’t found in their initial research - The Shadow Brokers/WannaCry connection they had missed - Specific dollar figures for economic damages from the Greek surveillance breach - Insurance industry risk assessments that add credibility to their systemic failure claims
Within hours, their case evolves from “backdoors create vulnerabilities” with theoretical evidence to a comprehensive argument with historical proof, technical details, and quantified impacts.
(b) Responses they didn’t think of
This is where collective intelligence generates emergent insights. A team reads through opponent cases and discovers rebuttals they never anticipated:
The Con team running the “government resources” argument encounters Pro responses they hadn’t prepared for: - “Implementation costs exceed savings” – backed by evidence about the technical infrastructure required for lawful access systems - “Backdoors create new resource drains” – with data about cybersecurity incident response costs - “Warrant approval rates prove warrants aren’t the bottleneck” – a statistical argument they hadn’t considered
They immediately recognize these are strong objections., They: - Find counter-evidence showing implementation is a one-time cost versus ongoing savings - Develop responses about how secure backdoor infrastructure costs less than current workarounds - Create a new analytical framework distinguishing between “obtaining warrants” (easy) and “executing warrants” (currently impossible with encryption)
The Con team running economic impacts discovers Pro teams are responding with: - “Speculative harm versus proven crime costs” – a weighing argument about probability - “Companies will adapt and maintain consumer confidence” – evidence about post-breach recovery - “International competition argument is exaggerated” – data about US tech dominance
They write frontlines: - Evidence distinguishing between “recovery from individual breaches” versus “systemic encryption failure” - Historical analysis of cases where consumer trust, once lost, took decades to rebuild - Comparative risk analysis showing why systemic failures are categorically different from distributed harms
(c) Arguments other teams are making they aren’t prepared for
This is the most strategically crucial discovery: entirely new arguments that teams haven’t encountered or prepared for.
A Con team discovers Pro teams running a novel “democratic dissent” argument they haven’t seen: - Evidence about encryption protecting political dissidents, journalists, activists - International human rights framework - Slippery slope claims about government surveillance expanding beyond warrants - Historical examples of surveillance targeting civil rights movements
They realize this argument operates on a different values framework than their prepared responses. They need: - Evidence about how warrant requirements protect dissent (judicial oversight prevents abuse) - Constitutional analysis distinguishing lawful access from mass surveillance - Comparative examples from democracies with lawful access that still protect dissent - Turns about how criminal impunity (enabled by encryption) threatens democratic stability.
Round 3
Round 3 begins. They are Pro this time, and for once their racing tournament prep actually lines up with what they hear. Con runs a sleek, confident argument claiming that lawful access will undermine quantum computing security. The team almost smiles. They had prepped this exact point.
In rebuttal, they cleanly explain that quantum computing is not the same thing as cryptography, that quantum machines threaten certain encryption schemes but are not themselves “secured” in the way Con is describing, and that lawful access mechanisms operate at the level of implementation and policy, not quantum hardware. It is one of their clearest technical explanations of the tournament.
Then the judge’s face tightens.
The RFD comes back muddled. The judge talks about “quantum computers being hacked” and seems to treat quantum computing and encryption as interchangeable ideas. The ballot goes Con. The team loses.
Outside the room, the frustration explodes. One debater throws their flow down and mutters that the judge is an idiot. Another says the round was unwinnable if the judge did not understand basic technology. They are not wrong about what happened, but they are furious anyway.
The coach lets them vent for a moment, then cuts in.
“You know you didn’t understand the difference either,” he says. “Not until half an hour ago. Someone explained it to you in prep, you practiced the wording twice, and now it feels obvious. That’s how learning works.”
She keeps going. Debate is not about being right in the abstract. It is about translating ideas across gaps in knowledge. Judges are not stupid. They are human. They come in with different backgrounds, different vocabularies, different mental models. If you cannot explain a complex idea in a way that someone without your prep understands, that is not just their failure. It is also yours.
The loss still stings, but the point lands. If the activity is about anything, it is this. Learning how to talk to everyone, not just people who already agree with you or already know the terms.
What follows is controlled chaos: teams racing to prepare for arguments they now know exist.
Teams have discovered 8-10 major arguments on OpenCaselist they’re not prepared for. They have 1 hour for a lunch break to prepare. The coach makes strategic decisions:
“We’re seeing the child exploitation argument in 40% of Con cases. We need responses now. I want three of you researching encryption protecting children. Two of you finding alternative investigation evidence specific to exploitation cases. One person writing responses based on what we find. You have 60 minutes, then we’re cutting cards and flowing responses.”
Meanwhile, another squad member is scanning caselist for new evidence: “Team from Texas has FBI testimony we don’t have. Downloading now. This could strengthen our trafficking contention.”
A partnership divides labor: “You write frontlines to the economic adaptation argument. I’ll handle the implementation costs response. We’ll combine our blocks before Round 5.”
The evidence flow is continuous: - Download evidence from OpenCaselist - Evaluate source quality and argument strength - Integrate into existing blocks or create new responses - Practice explaining the argument - Load into case files for immediate access during Round 5
….And this continues, often late into the night.
By Sunday morning, every team has evolved significantly from Saturday night. Cases are stronger (better evidence from collective research). Rebuttal blocks are more comprehensive (responses to arguments encountered over 6 rounds plus arguments seen on OpenCaselist). Strategic adaptation is sophisticated (knowing what opponents are likely to run based on caselist trends).
Rounds 4+
The tournament progresses, with students debating in more rounds of competition, struggling to prepare and sharing and evolving knowledge.
{EK + SSR +FK + ICK + CK + CCL}
Between Tournaments & Knowledge Explosion (BTKE)
What’s happening here is much richer than “people share evidence.”
By the end of a single tournament, a topic has already gone through dozens or hundreds of rapid stress tests. Every round generates new claims, new warrants, new impact frames, and new ways of phrasing the same idea. Teams are not just debating each other. They are implicitly making experiments on arguments in front of different judges, under time pressure, with real competitive consequences.
Now zoom out a bit.
On a typical weekend, the same resolution is being debated at dozens of tournaments across the country, sometimes across the world. That means thousands of rounds happening in parallel. Each round is a small trial: Does this argument land? Does this framing persuade? Does this evidence survive crossfire? Most arguments fail quietly. They sound good in prep and fall flat in the room. Others survive but only in narrow conditions. A few consistently work.
Those are the ones that spread.
When the Con team asks where the domestic violence evidence came from, that moment matters. The Pro team is not guarding a secret. They are pointing to a node in a network. A report, a study, a legal brief, a framing that suddenly made judges see encryption differently. Once shared, that evidence stops belonging to one team. It becomes part of the ecosystem.
By the next tournament, five teams are cutting the same card, but they are not copying it verbatim. One team shortens it. Another pairs it with a new impact. A third reframes it emotionally instead of technically. Someone figures out how to explain it to a lay judge in twelve seconds. Someone else finds a stronger warrant or a newer study. The argument evolves.
Over time, weak versions die out. Stronger versions replicate. The community collectively figures out which explanations are intuitive, which analogies stick, which impacts judges actually weigh. No single debater controls this process. No coach designed it from the top down. It emerges from repetition, competition, and sharing.
That is why the “case list” explodes. It is not just a list of arguments. It is a living archive of what has been tried, refined, discarded, and improved. Debate rewards originality, but it runs on recombination. New arguments are almost always built out of existing parts, rearranged in smarter ways.
Seen this way, a debate tournament looks less like isolated performances and more like a distributed research lab. Knowledge is produced socially, filtered competitively, and transmitted fast. By the time the season ends, the community knows far more about the topic than any individual team could have discovered on its own.
{EK + SSR +FK + ICK + CK + CCL + BTKE}
EK = Existing Knowledge (students’ prior knowledge from past experiences)
SSR = Secondary Source Research (initial readings, videos, news coverage, current events)
FK = Foundational Knowledge (core issues that recur across topics - climate change, economic stability, etc.)
ICK = Initial Community Knowledge (case lists, brief companies, backfiles)
CK = Coach Knowledge (pattern recognition, what wins, argument evolution, persuasion strategies)
BTKE = Between Tournaments Knowledge Explosion (reactive and collaborative)
The Intelligence Explosion: How Knowledge Compounds Exponentially
The Non-Linear Nature of Knowledge Combination
The key insight is that these six knowledge sources don’t just add together—they multiply and catalyze each other, creating exponential rather than linear growth.
If knowledge development were merely additive, the formula would be: Total Knowledge = EK + SSR + FK + ICK + CK + BTKE
But that’s not how it actually works. Instead, the formula is closer to: Total Knowledge = (EK × SSR × FK × ICK × CK) ^ BTKE
Here’s why this creates an intelligence explosion:
Stage 1: Initial Multiplication (Pre-Tournament)
EK × SSR: Prior Experience Accelerates New Research
A student with existing knowledge (EK) doesn’t approach secondary source research (SSR) as a blank slate. Their prior experience:
Helps them identify relevant sources faster (pattern recognition)
Enables them to evaluate credibility more effectively
Allows them to connect new information to existing frameworks
Lets them skip basic concepts and dive into advanced material
Example: A student who debated surveillance last year (EK) researching encryption (SSR) immediately recognizes familiar territory—Fourth Amendment concerns, security vs. privacy tradeoffs, government overreach arguments. They don’t need to learn constitutional basics; they can immediately access graduate-level cryptography papers and legal scholarship. Their research velocity is 3-5x faster than a novice.
Mathematical intuition: If EK = 5 units of knowledge and SSR adds 10 units, the combination isn’t 15. It’s more like 5 × 10 = 50, because existing knowledge makes new research exponentially more productive.
SSR × FK: New Research Activates Foundational Patterns
When students do secondary source research (SSR) on a specific topic, they don’t just learn topic-specific facts. They activate foundational knowledge (FK)—recognizable patterns that recur across topics.
Example: While researching encryption backdoors (SSR), students encounter:
Economic arguments about market failures (FK: market economics recurs across topics)
Privacy vs. security tradeoffs (FK: rights balancing recurs constantly)
Federalism questions about state vs. federal jurisdiction (FK: constitutional structure recurs)
Slippery slope concerns about government power (FK: precedent reasoning recurs)
Each piece of new research doesn’t just add information about encryption—it strengthens foundational frameworks that apply to dozens of future topics. The student isn’t learning encryption policy in isolation; they’re building transferable analytical architecture.
Mathematical intuition: If SSR generates 10 insights and FK provides 8 frameworks, you don’t get 18 units. You get 10 × 8 = 80, because every new insight can be understood through multiple frameworks, and every framework gains new applications.
ICK × CK: Community Knowledge + Coach Expertise = Strategic Acceleration
Initial Community Knowledge (ICK)—case lists, briefs, backfiles—provides raw material. Coach Knowledge (CK) provides strategic filtering and contextualization.
Example: A team downloads 50 cases from OpenCaselist (ICK). Without coach input, they’d spend hours reading mediocre arguments, testing weak positions, and reinventing solutions to solved problems. With coach knowledge (CK), they:
Immediately identify which 5 cases represent the strongest strategic approaches
Understand why certain arguments won at elite tournaments but won’t work with local judges
Recognize which evidence is outdated or methodologically flawed
See connections between arguments that aren’t obvious from reading cases linearly
Know which “new” arguments are actually recycled versions of arguments that failed years ago
Mathematical intuition: ICK might provide 100 units of raw information. But 80% of it is noise, redundancy, or context-dependent. CK acts as a 10x multiplier by filtering signal from noise and adding strategic context. So instead of 100 + 10 = 110, you get 100 × 10 = 1000 units of actionable intelligence.
Stage 2: The Between-Tournaments Knowledge Explosion (BTKE)
This is where exponential growth becomes explosive.
BTKE = Reactive, Collaborative, Real-Time Knowledge Synthesis
Between tournaments, several catalytic processes occur simultaneously:
1. Parallel Processing Across Hundreds of Teams
After a tournament weekend, hundreds of teams simultaneously:
Post cases to OpenCaselist (sharing what worked)
Identify gaps in their preparation (what they lost to)
Research responses to arguments they encountered
Refine evidence and strategic approaches
Test new frameworks
This is parallel computation on a massive scale. If 500 teams each spend 10 hours refining arguments between tournaments, that’s 5,000 hours of collective cognitive labor happening simultaneously. The community doesn’t think sequentially; it thinks in parallel.
2. Adversarial Testing Creates Rapid Selection Pressure
Arguments that survive tournament testing are proven to be persuasive under adversarial conditions. This is completely different from academic peer review (which is friendly and slow) or classroom assessment (which isn’t adversarial).
Example Evolution:
Week 1: Team A runs “encryption helps trafficking” argument with basic FBI statistics
Tournament 1: Team B defeats it with “alternative investigation methods” response
Between tournaments: Team A finds evidence that alternatives take months while victims suffer daily
Tournament 2: Team A’s refined argument beats the “alternative methods” response
Between tournaments: Team B discovers that Team C has evidence about international trafficking using foreign apps beyond US jurisdiction
Tournament 3: Now three arguments are clashing, forcing Team A to develop “even if some traffickers switch services, stopping the majority saves thousands of lives”
Between tournaments: All three lines of argument (trafficking harms, alternative methods, international evasion) are now posted on OpenCaselist and being tested by 50+ teams simultaneously
Within 4 weeks, an argument has gone through 3+ generations of evolution, tested across hundreds of rounds, with refinements contributed by dozens of teams. This would take years in traditional academic discourse.
3. Recombinant Innovation
The real intelligence explosion happens when knowledge sources recombine in novel ways.
Example:
Student A (EK: economics background) researches cybersecurity insurance markets (SSR)
Student B (FK: constitutional law) recognizes this connects to takings clause questions
Student C (ICK: reading backfiles) finds a similar economic argument worked on a different topic 2 years ago
Coach D (CK: strategic insight) realizes this combination defeats the standard “speculative impact” response
During BTKE, they synthesize: Economic analysis + constitutional framework + historical precedent + strategic positioning
This novel synthesis gets posted to OpenCaselist. Within days:
Team E adapts it for different impact scenarios
Team F finds better evidence supporting the economic mechanism
Team G discovers a counterargument about moral hazard in insurance markets
Team H develops a framework response about weighing economic versus rights-based impacts
One innovation triggers dozens of derivative innovations. This is recombinant explosion—the number of possible combinations grows factorially as components increase.
4. Cross-Pollination Between Squads
Knowledge doesn’t stay siloed within individual squads:
Teams compete against each other and see novel approaches
Judges circulate across circuits, spreading strategic insights
Online forums discuss argument quality
Coaches talk to other coaches
Case lists make everything transparent
This is knowledge liquidity. Good ideas flow frictionlessly across the network. There’s no institutional barrier preventing a small-town team from accessing the same strategic insights as elite private school programs.
Why This Creates an Intelligence Explosion
Definition: An intelligence explosion occurs when improvements to a system’s intelligence enable it to make further improvements faster, creating a positive feedback loop that accelerates exponentially.
In the debate context:
Cycle 1 (Pre-Season/1st 3o days):
Students start with EK + some SSR + basic FK
Time to develop competitive case: ~20 hours
Quality: Basic arguments, basic evidence, predictable structure
Cycle 2 (Post-Tournament 1):
Students now have: EK + SSR + FK + ICK (from seeing opponents) + CK (coach feedback) + BTKE (community refinement)
Time to improve/modify/change competitive case: ~5 hours (they’re faster now, ideas move quicklyy)
Quality: Intermediate arguments, tested evidence, strategic adaptation
Cycle 3 (Post-Tournament 3):
Students now have: Enhanced EK (learned from experience) + Deep SSR (know the literature) + Robust FK (pattern recognition automatic) + Rich ICK (hundreds of cases studied) + Internalized CK (strategic thinking habitual) + Massive BTKE (3 cycles of community evolution)
Time to develop competitive case: ~10+ hours
Quality: Sophisticated arguments, cutting-edge evidence, strategic innovation
Cycle 5 (End of topic tournaments):
Time to develop competitive case: ~10+ hours
Quality: Nationally competitive arguments that incorporate insights from hundreds of teams, tested across thousands of rounds, refined through multiple cycles of adversarial engagement
The acceleration is exponential because:
Each cycle makes the next cycle faster in terms of what can be accomplished in the alloted time (learning compounds)
Each cycle makes the next cycle higher quality (standards rise)
Each cycle involves more participants (network effects grow)
Each cycle builds on all previous cycles (knowledge accumulates, doesn’t reset)
The Mathematical Model
A simplified model of the intelligence explosion:
Tournament 1:
Knowledge = (5 EK × 10 SSR × 8 FK × 20 ICK × 15 CK) = 120,000 units
Amplified by BTKE (let’s say 2x multiplier first cycle) = 240,000 units
Tournament 2:
Previous knowledge becomes new baseline EK = 240
New SSR builds on this (10 × 240) = 2,400
FK is now richer (8 × 240) = 1,920
ICK has expanded (now 40 cases reviewed) = 40
CK is more sophisticated (now 25) = 25
Knowledge = (240 × 2,400 × 1,920 × 40 × 25) = 4.6 billion units
BTKE multiplier is now 3x (more teams, more data) = 13.8 billion units
Tournament 3:
The numbers become astronomical
This is obviously a toy model based on rough numbers, but it captures the core dynamic: each cycle doesn’t add a constant amount—it multiplies by an increasing factor.
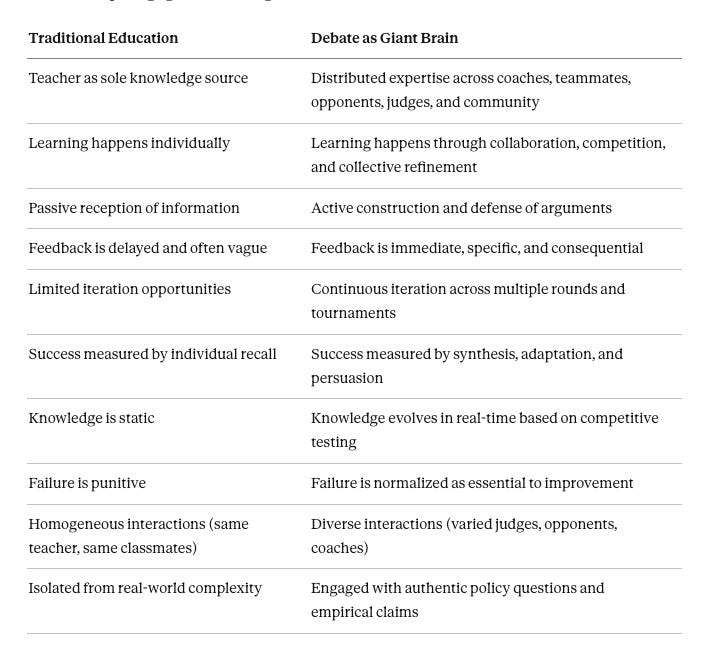
Why Traditional Education Doesn’t Create This Explosion
Traditional education lacks the key catalysts.
No BTKE equivalent: Students don’t rapidly share what they learned, test it adversarially, and collectively refine it between assignments. Each student’s learning is isolated.
Limited ICK: Students can’t easily access what other students produced (without “cheating”), learn from their approaches, or build on their work.
Delayed/weak CK: Teacher feedback comes slowly, often after the learning opportunity has passed, and doesn’t have the density of pattern recognition that comes from observing hundreds of iterations.
No parallel processing: When 30 students work on the same problem in traditional classrooms, they work independently. Their insights don’t rapidly combine. In debate, when 500 teams work on the same topic, their insights synthesize continuously through competition and case sharing.
No adversarial testing: Traditional assessment isn’t adversarial. Students aren’t trying to expose each other’s weaknesses. There’s no selection pressure eliminating bad ideas quickly.
Knowledge resets between units: When a traditional class moves from “unit on encryption” to “unit on climate policy,” student knowledge largely resets. In debate, FK and CK transfer completely, EK grows, and even ICK partly transfers (argument structures, evidence evaluation skills, strategic frameworks all apply to new topics).
The Result: Superhuman Learning Velocity
By mid-season, competitive debaters often understand policy issues better than:
Adults who casually follow the news
College students taking relevant courses
Many professionals outside specialized fields
This seems impossible—how can a 16-year-old understand encryption policy better than educated adults after just 8 weeks of research?
The intelligence explosion explains it:
The student isn’t learning alone. They’re plugged into a distributed cognitive system that has collectively invested tens of thousands of hours in parallel research, adversarial testing, rapid iteration, and collaborative refinement. They have access to:
Evidence compiled by hundreds of teams
Arguments tested across thousands of rounds
Strategic insights from dozens of coaches
Frameworks refined through multiple evolutionary cycles
Real-time feedback from competitive outcomes
Their individual intelligence hasn’t increased supernaturally. They’ve learned to function as an effective node in a collective intelligence system that can process information orders of magnitude faster than individual cognition or traditional education.
That’s the intelligence explosion.
The combination of EK × SSR × FK × ICK × CK creates a baseline. Then BTKE acts as an exponential multiplier that compounds each cycle, creating runaway acceleration in collective knowledge quality, depth, and sophistication.
It’s not magic. It’s mathematics. It’s network effects. It’s evolutionary selection. It’s distributed cognition operating at scale.
And it’s exactly how the future of learning, working, and knowledge creation will operate—whether we’re talking about human networks or AI systems.
Idea Evolution
At a simple level, this process mirrors what philosopher Karl Popper called “evolutionary epistemology”—knowledge grows through bold conjectures and rigorous testing. Arguments are proposed (conjecture), subjected to adversarial scrutiny (testing), and either survive or are eliminated (selection). Biologist David Hull applied this model directly to scientific communities, showing how competition among researchers operates like natural selection, with weaker theories eliminated and stronger ones proliferating.
Judges provide written feedback: “Your cybersecurity impact was compelling, but you need to explain WHY backdoors can’t be secured rather than just asserting it.” “The organized crime evidence was emotionally powerful, but your opponents’ alternative investigation methods went unanswered.” “You won on magnitude, but they won on probability, and you never explained why I should prioritize magnitude over probability.”
Coaches refine strategies: “We’re seeing teams respond to our cybersecurity argument by claiming it’s too abstract. We need more specific scenarios—power grid attacks, hospital ransomware, financial system compromises. Find evidence about what happened when the Equifax breach occurred or when Colonial Pipeline was attacked.”
Students adapt continuously. By the fourth tournament, strong teams have: - Refined their cases based on 15-20 rounds of testing - Encountered most major opposing arguments and developed responses - Identified which pieces of evidence judges find most persuasive - Learned which explanations work in cross-examination and which create confusion - Adjusted their weighing to address the specific clash points that emerge most often
Younger students borrow from more experienced teams, learning the structure of effective argumentation. A novice team sees a strong cybersecurity case on OpenCaselist and adopts it. But they quickly learn they can’t just read the evidence—they need to understand it well enough to answer questions in cross-examination, respond when opponents present contrary evidence, and explain complex technical concepts clearly to judges who might not have computer science backgrounds.
Stronger teams innovate, finding novel applications of evidence or developing creative frameworks. One elite team might discover academic research on “cryptographic agility”—the ability of systems to switch encryption methods quickly if vulnerabilities are discovered. This becomes a new response to the “backdoors are vulnerable” argument: even if backdoors create risks, systems can adapt. But then other teams respond by finding evidence that cryptographic agility takes years to implement, not the immediate timeframe needed to prevent exploitation. The argument evolves.
Everyone contributes. A single student benefits from: - Their partner’s research and strategic insights - Opponents who test their arguments and expose weaknesses - Teammates who share successful responses and evidence - Coaches who identify patterns across multiple rounds and tournaments - Judges who explain what they found persuasive and what needed more development - Past debates on surveillance, privacy, and technology topics that provide analytical frameworks - The accumulated wisdom of hundreds of teams posting cases, sharing evidence, and iterating on arguments
No one is thinking alone. Every debater is a node in a larger network of distributed intelligence.
Social epistemologists like Alvin Goldman and Helen Longino have argued that knowledge is inherently social—objectivity emerges not from individual minds but from community processes of criticism and refinement. Longino calls this “transformative criticism”: knowledge claims are refined through rigorous community scrutiny. Debate’s adversarial structure embodies this mechanism. Every argument faces immediate, motivated criticism from opponents who benefit from exposing weaknesses.
Why This Accelerates Learning
This system produces learning faster and more durably than almost any traditional classroom model, for several reasons.
Immediate Testing
In most classes, students write papers or take exams weeks after learning material. In debate, arguments are tested within days of construction and refined within hours based on whether they persuade judges and withstand rebuttal.
Feedback is immediate, specific, and consequential. A judge doesn’t write “needs more development” on a paper three weeks later. They announce after 5+ minutes of deliberation: “I voted Con because while Pro won the cybersecurity impact on magnitude, Con won the probability debate and explained why I should prioritize preventing certain harms over possible future risks.” The student knows exactly what didn’t work and can adjust immediately.
Naomi Winstone & David Carless’s research on “feedback spirals” distinguishes single-loop feedback (improving immediate performance) from double-loop feedback (re-evaluating fundamental approaches). Debate creates continuous feedback spirals where students tackle challenges, engage with specific criticism, reflect on what worked, and make ongoing adjustments across multiple tournaments. Research by John Hattie has established feedback as among the most powerful influences on learning, with highly significant effect sizes.
Public Accountability
Bad reasoning is exposed not in private written comments but in front of judges, opponents, and teammates. Students cannot hide weak arguments or unclear logic.
For instance, a student might include evidence claiming that “most cybersecurity experts oppose encryption backdoors.” In cross-examination, the opponent asks: “Who specifically? Your evidence doesn’t cite any experts by name. Is this a survey, or just an assertion?” The student realizes their evidence is weak. But it’s worse than just realizing it privately—they’ve just admitted in front of the judge that they don’t actually know who these experts are or what study the evidence comes from. The judge writes in their decision: “Pro’s cybersecurity argument relied on evidence that, when questioned, they couldn’t defend. This suggests they didn’t fully understand their own research.”
That’s a powerful learning moment. The adversarial structure forces clarity and precision. By the next tournament, that student has replaced vague expert claims with specific citations: “Schneier 2023, cryptographer and security expert, argues…” and “Survey of 400 cybersecurity professionals published in Journal of Cybersecurity finds 73% oppose…”
Rapid Iteration
A debater might run the same core argument ten times in a month, each time facing different objections, different evidence, and different judges. Repetition is not mindless. Each iteration refines understanding, reveals new weaknesses, and suggests strategic adjustments.
Track the evolution of the “organized crime” argument across a season:
Week 1: “Encryption helps criminals evade prosecution. We need backdoors to catch them.” - Loses most rounds because it’s too vague and doesn’t specify what crimes or provide evidence
Week 2: “FBI statistics show encryption hindered 7,800 investigations in 2023. Evidence about child exploitation cases where encrypted communications prevented rescues.” - Wins more rounds because it’s concrete, but loses to responses about alternative investigation methods
Week 3: Adds frontlines: “Alternative methods are insufficient. Evidence shows undercover operations take years and are dangerous. Time-sensitive cases like kidnappings require immediate access.” - Better win rate, but loses to arguments about how even with backdoors, criminals can use foreign-based encrypted services
Week 4: Develops new weighing: “Even if some criminals switch to foreign services, reducing accessibility to simple encrypted apps stops the vast majority of non-sophisticated criminals. Evidence that most child exploitation networks use consumer apps like WhatsApp, not specialized foreign services.” - Much stronger. Now winning against most Pro teams.
Week 5: Opponents have adapted. They’re running evidence that criminal organizations are sophisticated and will adapt regardless. The argument needs another evolution.
This is deep, iterative learning that produces genuine expertise. By the end of the topic, strong debaters understand the issue better than most adults, including many teachers. They know: - The major arguments on both sides - The best evidence available, including which studies are most methodologically sound - The logical tensions within each position (e.g., how advocating for backdoors creates a tension between security and law enforcement effectiveness) - The strategic landscape of how different claims interact - How to answer sophisticated objections they’ve encountered dozens of times - Which impacts judges find most persuasive and why - How experts in cryptography, law enforcement, constitutional law, and cybersecurity think about these tradeoffs
Of course, that depth emerges from collective intelligence, not isolated genius.
Distributed Cognition
Students learn from everyone they encounter. A single tournament exposes a debater to dozens of different arguments, analytical approaches, evidence sources, and strategic choices. That learning accumulates across the season.
Imagine a student from a small school in rural Montana. Their coach is a first-year English teacher with no debate background. Without the collective brain, this student would be limited by their coach’s knowledge and their school’s resources.
But at their first tournament, they hit teams from: - A well-funded private academy whose coach is a former national champion - A public school team whose coach specializes in constitutional law - A team from an urban district with extensive backfiles from five years of past topics - A homeschool team whose coach is a retired attorney
Each round exposes them to new evidence, new argument structures, new strategic approaches. They see cases posted on OpenCaselist from teams in California, Texas, New York, Florida. They read judge feedback from attorneys, college professors, former debaters, and community judges with different backgrounds. They watch elimination rounds online where the best teams in the country clash.
By mid-season, that Montana student has access to the same intellectual resources as the private academy student. They’ve seen the best arguments, encountered the strongest evidence, learned from top coaches’ strategic insights (embedded in the cases their students run), and benefited from the collective wisdom of thousands of participants.
The distributed brain eliminates resource disparities. Knowledge becomes democratized.
This validates James Surowiecki’s thesis in The Wisdom of Crowds: under the right conditions, groups are remarkably intelligent and often smarter than the smartest individuals in them. Four conditions enable wise crowds: diversity of opinion, independence of decision, decentralization of organization, and effective aggregation mechanisms. Debate communities satisfy these conditions through diverse debater perspectives (geographic, socioeconomic, ideological), independent team preparation, decentralized research and innovation, and tournament results as aggregation mechanisms that identify superior arguments.
That depth emerges from collective intelligence, not isolated genius.
The Interdisciplinary Architecture of Collective Intelligence
One of debate’s most powerful but underappreciated features is how it develops interdisciplinary knowledge across multiple dimensions simultaneously. Unlike traditional education, which compartmentalizes learning into discrete subjects, debate creates what organizational theorists call a “multifunctional team structure” where different forms of expertise converge on shared problems.
More: Multiple Students, Multiple Coaches: Distributed Specialization
Consider the cognitive architecture of a competitive debate squad. No single student or coach possesses all the knowledge required for success. Instead, expertise distributes across the system:
Research specialists develop deep content knowledge. On the encryption topic, one student might specialize in cybersecurity research, reading academic papers from cryptographers and computer scientists. Another might focus on constitutional law, studying Fourth Amendment jurisprudence and Supreme Court precedent. A third might specialize in criminology, gathering evidence about law enforcement investigations and criminal behavior patterns. Each brings domain-specific expertise that no individual could master alone.
Technical specialists develop methodological skills. Some students excel at evidence comparison—evaluating study quality, identifying methodological flaws, assessing external validity. Others specialize in logical analysis—constructing validity tests, identifying hidden assumptions, exposing contradictions. Still others focus on strategic planning—anticipating opponent moves, developing decision trees, optimizing time allocation.
Communication specialists develop audience adaptation skills. Certain debaters excel at explaining complex technical concepts to lay judges. Others specialize in persuading former debaters who value technical precision. Some develop expertise in cross-examination psychology—reading opponent tells, maintaining composure under pressure, exploiting weaknesses.
This mirrors how corporations organize around specialized functions. James March and Herbert Simon’s research on organizational intelligence showed that effective organizations distribute cognitive labor across specialists who contribute different forms of expertise. The organization’s intelligence emerges from coordinating these specialized capabilities, not from any individual’s comprehensive knowledge.
In a debate squad of 15 students with three coaches, you might find:
A coach who is a lawyer, providing constitutional analysis
A coach who is a former national circuit champion, offering strategic expertise
A coach who is a high school teacher, understanding pedagogical scaffolding
A student who excels at economic research
A student who specializes in international relations
A student with computer science background for technology topics
A student who is exceptional at explaining complex ideas simply
A student who thrives under cross-examination pressure
When the squad prepares for the encryption topic, the computer science student explains cryptographic architecture, the pre-law student researches Fourth Amendment precedent, the economics student analyzes market effects of regulation, the international relations student finds evidence about global surveillance cooperation, and the communication specialist figures out how to make it all persuasive to parent judges.
No individual student learns everything. But the squad collectively develops comprehensive expertise across:
Content domains: Computer science, constitutional law, criminology, economics, international relations, risk analysis, ethics, public health (depending on the topic)
Methodological skills: Statistical analysis, legal reasoning, cost-benefit analysis, comparative case studies, causal inference, counterfactual reasoning
Communication competencies: Technical translation, audience analysis, persuasive framing, nonverbal communication, question deflection, narrative construction
This is genuinely interdisciplinary knowledge development—not superficial exposure to multiple fields, but deep engagement where students must integrate insights across domains to construct coherent arguments.
The Cognitive Science of Distributed Intelligence
To understand why debate functions as collective intelligence, we need to examine what cognitive scientists call “distributed cognition.”
In his landmark 1995 book Cognition in the Wild, cognitive anthropologist Edwin Hutchins revolutionized how we think about intelligence. Through detailed observation of naval navigation teams, Hutchins demonstrated that cognition is not confined to individual brains. Instead, cultural activity systems have cognitive properties that emerge from the interaction of people, tools, and social organization.
Hutchins identified three ways cognition distributes:
Across social groups: Knowledge is held collectively by teams, with no single individual possessing complete understanding. Naval navigation requires coordinating information across multiple crew members, each with specialized knowledge.
Between internal and external structures: Tools like charts, instruments, and written procedures serve as external cognitive resources that genuinely extend thinking capacity, not merely assist it.
Through time: Knowledge accumulates across generations as procedures, artifacts, and cultural practices preserve and transmit understanding.
This framework transforms how we understand debate. The appropriate unit of analysis is not the individual debater but the partnership, squad, or community. System-level cognitive properties—the quality of arguments that emerge, the speed of knowledge refinement, the depth of topic expertise—cannot be reduced to individual intelligence.
Philosophers Andy Clark and David Chalmers extended this insight in their influential 1998 paper “The Extended Mind.” They argued that external objects can become genuinely cognitive when they function with the same purpose as internal mental processes. Their famous thought experiment compared Otto, who uses a notebook for memory due to Alzheimer’s, with Inga, who relies on biological memory. When Otto consults his notebook, that consultation is functionally equivalent to Inga remembering. The notebook is not merely a tool Otto uses; it is part of his cognitive system.
The key criterion for cognitive extension is functional equivalence: if the external resource is reliably available, automatically endorsed, and serves the same role as biological memory or reasoning, then it genuinely constitutes part of the mind.
By this standard, debate’s artifacts are cognitive components, not just helpful tools. Evidence files that debaters access automatically during prep time function equivalently to remembered knowledge. Flow sheets that track arguments across speeches serve the same purpose as working memory. Case outlines that structure thinking operate like internal schemas. These are not metaphors. They are genuine extensions of debaters’ cognitive systems.

Research on what cognitive scientists call “transactive memory systems” further illuminates how partnerships function. Psychologist Daniel Wegner showed that groups develop collective memory through specialization (members possess distinct knowledge), coordination (members work together smoothly when accessing knowledge), and credibility (members trust each other’s expertise). Effective debate partnerships exemplify transactive memory: one partner specializes in certain arguments or evidence, the other knows who holds which knowledge, and both trust their partner’s expertise. The system remembers more than either individual could alone.
Recent research on collective intelligence by Anita Woolley and Thomas Malone discovered that groups have a collective intelligence factor—analogous to individual IQ—that predicts performance across diverse tasks. Critically, group intelligence was not strongly correlated with the average or maximum individual intelligence of members. Instead, three factors mattered: social sensitivity (the ability to read others’ mental states), equality in conversational turn-taking, and collaborative dynamics.
This finding has profound implications: the smartest debate squad is not necessarily the one with the highest individual IQs. It’s the one with strong relational dynamics, equal participation, and social awareness. Debate’s cognitive power emerges from system properties, not individual genius.
AI Integration: Increasing Interdisciplinary Bandwidth
When AI tools enter this system, they don’t replace the interdisciplinary architecture—they amplify it.
Consider how AI changes knowledge access across domains:
Before AI: A student researching the encryption topic might spend hours finding relevant computer science papers, struggle to understand cryptographic concepts without background knowledge, miss connections to economic analysis of cybersecurity markets, and overlook relevant legal precedents outside their search terms.
With AI: The same student can ask ChatGPT to explain elliptic curve cryptography in accessible terms, identify the economic literature on cybersecurity insurance markets, find relevant Fourth Amendment cases involving digital privacy, and suggest connections between encryption policy and international trade law. The AI serves as an interdisciplinary translator and connection-maker.
But—and this is critical—the AI doesn’t eliminate the need for human interdisciplinary thinking. Instead, it increases the bandwidth of knowledge that individual students can engage with, which then gets tested and refined through the distributed debate system.
A student might use AI to: - Translate technical cybersecurity concepts into lay terms (AI as interdisciplinary translator) - Identify connections between encryption policy and topics they debated previously (AI as pattern recognition) - Find relevant evidence across multiple academic disciplines simultaneously (AI as cross-domain search) - Generate initial frameworks combining legal, technical, and economic analysis (AI as synthesis tool)
Then the distributed system stress-tests these AI-assisted insights:
Opponents challenge the technical accuracy (exposing AI errors or oversimplifications)
Judges evaluate whether the interdisciplinary connections are persuasive (testing integration quality)
Coaches identify gaps in cross-domain reasoning (revealing where synthesis breaks down)
Tournament iteration rewards genuine interdisciplinary understanding over superficial connections
Research on human-AI collective intelligence suggests this is optimal: AI tools that augment human cognitive diversity rather than replacing it enhance collective problem-solving. When AI helps a student access economic analysis they wouldn’t have found alone, that increases the squad’s interdisciplinary knowledge pool. When multiple students use AI to explore different domains (one focuses on technical literature, another on policy analysis, another on ethical frameworks), the collective knowledge base expands faster than any individual could achieve.
The result is accelerated interdisciplinary learning. Students engage with content and methods from computer science, law, economics, political science, ethics, psychology, and statistics—not in isolated units but in integrated problem-solving contexts where they must synthesize across domains to win debates.
Knowledge Iteration and Development Velocity
The distributed, interdisciplinary structure dramatically increases the speed at which knowledge develops and refines.
Compare traditional academic knowledge development to debate’s system:
Traditional academic research: - Researcher develops hypothesis (months) - Conducts study (months to years) - Submits to journal (immediate) - Peer review process (3-12 months) - Revisions (months) - Publication (months after acceptance) - Community engagement (years) - Replication and validation (years) - Integration into consensus (years to decades)
Total timeline: Often 5-10 years from initial insight to validated consensus
Debate knowledge development: - Team develops argument (days to weeks) - Tests at tournament (weekend) - Receives immediate feedback from judges and opponents (same day) - Refines based on what worked/failed (between rounds, same weekend) - Posts to OpenCaselist (immediately after tournament) - Other teams adopt, adapt, or challenge (within days) - Community consensus emerges on argument quality (2-3 weeks) - Argument either becomes standard or disappears (by mid-season)
Total timeline: 4-6 weeks from initial idea to community consensus
The velocity difference is 50-100x faster than traditional academic knowledge development.
Why? Several compounding factors:
Parallel processing: Hundreds of teams develop variations simultaneously rather than sequential individual efforts. When the encryption topic drops, 500 teams aren’t waiting for one team to publish their research—all 500 are exploring the problem space concurrently.
Rapid testing cycles: Weekend tournaments provide 4-6 empirical tests (rounds) of each argument, with immediate results. No waiting months for peer review—you know by Sunday afternoon whether your argument works.
Competitive selection pressure: Arguments that fail get abandoned immediately rather than lingering in literature for years. There’s no incentive to defend a losing argument—you just try something better next tournament.
Open sharing norms: OpenCaselist creates radical transparency. Imagine if scientists published all their working hypotheses, failed experiments, and successful methodologies in real-time. That’s debate’s knowledge-sharing culture.
Distributed validation: Instead of 2-3 anonymous peer reviewers, each argument gets evaluated by dozens of judges across multiple tournaments, providing diverse perspectives and reducing idiosyncratic bias.
Interdisciplinary integration: Because debaters must synthesize across domains to construct cases, cross-domain connections emerge and get tested much faster than in siloed academic disciplines.
This explains why debaters often understand policy issues better than adults after just 2-3 months of research. They’re not just reading more—they’re participating in a knowledge development system that iterates 50x faster than traditional learning.
The addition of AI accelerates this further. When students can use AI to quickly explore adjacent domains, identify relevant evidence across disciplines, and generate initial synthetic frameworks, the ideation phase compresses from weeks to days. When hundreds of teams are all using AI-assisted research simultaneously, the collective exploration of the problem space becomes even more comprehensive.
But the testing and validation still happens through human judgment—judges evaluating persuasiveness, opponents exposing logical flaws, coaches identifying strategic weaknesses. AI speeds up knowledge acquisition; the distributed debate system speeds up knowledge validation and refinement.
Organizational Intelligence: The Corporate Parallel
The debate squad’s structure bears remarkable similarity to how corporations organize cognitive labor, as described in organizational behavior research.
Functional specialization: Just as corporations have R&D departments, marketing teams, legal counsel, and operations specialists, debate squads develop functional roles. Some students specialize in research and evidence gathering (R&D). Others focus on strategy and competitive analysis (business intelligence). Still others specialize in presentation and persuasion (marketing/sales). Coaches provide oversight and coordination (management).
Cross-functional project teams: When preparing for a specific topic, squads form cross-functional teams that combine specialists. The encryption topic case might be developed by: the computer science specialist (technical accuracy), the pre-law student (constitutional analysis), the strong communicator (judge adaptation), and a strategic thinker (anticipating opponent responses). This mirrors how corporations assemble cross-functional teams for complex projects.
Knowledge management systems: Evidence databases, backfiles, and case libraries function as corporate knowledge management systems—organizational memory that persists beyond any individual. When a senior graduates, their research and cases remain, like documented procedures in a company.
Competitive intelligence: Teams scout opponents, analyze competing strategies, and adapt based on what’s working in the broader community. This parallels corporate competitive analysis.
Performance metrics and accountability: Tournament results provide clear performance feedback, like corporate KPIs. Win-loss records, speaker points, and judge feedback create accountability and identify areas for improvement.
The key insight from organizational intelligence research is that smart organizations are not just collections of smart individuals. They require coordination mechanisms, information flows, decision-making structures, and learning processes that enable collective intelligence to emerge.
James March’s work on “organizational learning” showed that organizations face a fundamental tension between exploitation (using existing knowledge efficiently) and exploration (developing new knowledge). Successful organizations balance both.
Debate squads do this naturally:
Exploitation: Using proven arguments and strategies that work (running the strong cybersecurity case that won the last tournament)
Exploration: Testing new arguments and approaches (trying the novel framework about national security exceptions)
Tournament structure enforces this balance. Preliminary rounds reward exploitation (run what works to qualify). Elimination rounds often reward exploration (opponents have scouted your standard strategy, so innovation becomes necessary).
The corporate parallel extends to incentive structures. Like corporations, debate squads face collective action problems: individual success (winning speaker awards) sometimes conflicts with team success (winning the tournament). Effective squads develop cultures that balance individual achievement with collective contribution—sharing evidence generously, helping younger students improve, and prioritizing team advancement.
Research on “transactive memory in organizations” shows that high-performing teams develop shared knowledge about who knows what—metamemory that enables efficient coordination. Debate partnerships exemplify this: successful teams know their partner’s strengths and weaknesses, who has which evidence, and who should handle which arguments. “You take the cybersecurity responses, I’ll handle the constitutional analysis” divides cognitive labor efficiently.
The distributed cognition framework helps explain why debate produces such rapid skill development: it’s not just individual learning but organizational intelligence formation. Students aren’t just becoming smarter individually—they’re learning to participate in intelligent organizations, developing skills in knowledge coordination, specialization, communication protocols, and collective problem-solving that transfer directly to professional contexts.
Learning to Be a Node: Debate as Training for Networked Intelligence
The Obsolete Model of the Isolated Mind
Picture the traditional classroom: thirty students, thirty desks, thirty closed notebooks. The teacher lectures. Students take notes. Eventually, they sit alone at those desks, take a test, and demonstrate what they individually remember and can individually reproduce. The implicit theory of intelligence is clear: learning happens inside isolated skulls, and education’s job is to fill those skulls with information that can be retrieved on demand.
This model made sense for a world where knowledge was scarce, retrieval was difficult, and most professional work required individuals to solve problems with the information they could personally hold in memory. A lawyer needed to know the law. An accountant needed to know tax codes. A doctor needed to memorize symptoms and treatments. Success meant having the right information stored in your individual brain and being able to access it when needed.
That world is ending—or more precisely, it has already ended, and education hasn’t caught up.
In the world students are actually entering, almost all information is instantly accessible, retrieval is trivial, and competitive advantage comes not from what you personally remember but from how effectively you can:
Navigate vast information networks to find what matters
Evaluate the credibility and relevance of what you find
Synthesize insights across multiple sources and domains
Collaborate with others who have complementary expertise
Adapt rapidly when new information challenges existing assumptions
Contribute to collective knowledge systems that benefit from your participation
These are not skills you develop by sitting alone at a desk trying to remember facts. These are skills you develop by functioning as a node in a distributed intelligence network—exactly what debate training provides.
Debate as Network Literacy
When students enter competitive debate, they are immediately confronted with a truth that traditional education obscures: they cannot succeed alone, and they shouldn’t try.
A novice debater’s first tournament is often disorienting. They walk in with a case they wrote (or think they wrote) and immediately discover:
Their opponents are running arguments they’ve never heard before
Other teams have evidence they didn’t know existed
Judges evaluate arguments using frameworks they haven’t considered
Their teammates are sharing information in real-time through group chats and Discord servers
An entire ecosystem of shared knowledge—OpenCaselist, evidence databases, backfiles—has been operating before they arrived
The question is not “Will I need to plug into this network?” It is “How quickly can I learn to function effectively within it?”
This is precisely the situation every professional will face in their career. You don’t get hired to work in isolation. You get hired to join an existing organizational intelligence system with established protocols, shared knowledge bases, distributed expertise, and collaborative workflows. Your value comes not from what you alone know but from how effectively you can contribute to and extract value from the collective system.
Debate teaches network literacy from day one:
Learning to locate knowledge: Where is the best evidence on this topic? Who has already researched this argument? What sources are credible? Which teams are running effective strategies? Students learn to navigate distributed information networks—not passively consuming what a teacher provides but actively hunting through academic databases, case lists, policy briefs, and peer discussions.
Learning to evaluate and filter: When you find six different pieces of evidence claiming opposite conclusions, how do you decide which to trust? Students develop critical filtering skills that transfer directly to professional contexts: assessing source credibility, identifying methodological flaws, distinguishing correlation from causation, recognizing motivated reasoning.
Learning to synthesize: How do you take insights from cryptography, constitutional law, criminology, and economics and integrate them into a coherent argument? This is the fundamental skill of knowledge work in interdisciplinary domains—and it cannot be learned by studying disciplines in isolation.
Learning to contribute: What can you add to the collective knowledge base? Students learn that contribution isn’t about generating entirely novel insights from scratch. It’s about finding better evidence, developing clearer explanations, identifying new connections, and testing claims more rigorously. This is how professional knowledge work actually operates.
Learning to adapt: When new information challenges your position, how quickly can you adjust? When opponents expose weaknesses in your argument, can you incorporate their critique and improve? Debate creates rapid iteration cycles that train adaptive thinking—the ability to update beliefs based on new evidence rather than defensively protecting existing positions.
The Node Mindset: Identity in Collective Intelligence
Traditional education treats individual achievement as the gold standard. The best students are those who can produce the most impressive individual work. Collaboration is often treated with suspicion—is this really your thinking, or did someone else help you?
This framing creates a fundamentally individualistic identity: I am smart to the extent that I, personally, can solve problems without help.
Debate inverts this. Success requires recognizing that you are not a self-contained intelligence competing against other self-contained intelligences. You are a node in a network, and your value comes from how effectively you connect, contribute, and leverage collective resources.
Consider what students learn about identity and capability through debate:
Partnership identity: You are not debating alone. You are half of a partnership. Success depends on knowing your partner’s strengths and weaknesses, dividing cognitive labor efficiently, and coordinating in real-time. The best individual debater paired with a mediocre partner will lose to a slightly-above-average partnership with excellent coordination.
This is a profound lesson about professional work. In almost no career will your success depend purely on individual capability. It will depend on how effectively you collaborate with colleagues who have complementary skills. The sooner students learn to think in terms of “we” rather than “I,” the better prepared they are for reality.
Squad identity: Your partnership is part of a larger squad. When your teammates discover strong evidence or effective strategies, you benefit. When you find something useful, you share it. The squad’s collective intelligence determines everyone’s success.
Students learn to be simultaneously competitive and collaborative—competing against other schools while cooperating intensely within their own squad. This mirrors organizational dynamics where teams compete for resources and recognition while cooperating to achieve shared goals.
Community identity: The squad is part of a broader debate community that spans schools, states, and even countries. When teams post cases on OpenCaselist, when judges provide written feedback, when online forums discuss argument quality, when students from different schools share evidence—the entire community becomes smarter together.
This is where the “giant brain” metaphor becomes literal. Individual neurons (debaters) form networks (partnerships and squads) that connect into larger structures (the national debate community). Knowledge propagates through these networks faster than any individual could develop it. Selection pressure operates at the community level, eliminating weak arguments and amplifying strong ones.
Professional identity: Ultimately, students are learning to identify as knowledge workers within a distributed intelligence system. Their role is not to be the smartest person in the room. Their role is to:
Contribute specialized expertise to collective problems
Synthesize insights from multiple contributors
Test claims through adversarial engagement
Iterate rapidly based on feedback
Help others access and build on their work
This is exactly what professionals do in research labs, legal teams, consulting firms, engineering departments, policy organizations, and virtually every other knowledge-intensive field.
From Information Scarcity to Information Abundance
The traditional education model emerged from information scarcity. When books were expensive and libraries were limited, memorization made sense. When expert knowledge was concentrated in teachers’ minds, lecture-based transmission made sense. When collaboration was difficult because people couldn’t easily share information across distance, individual work made sense.
Every one of those conditions has reversed:
Information is abundant, not scarce: Students have access to more information in their pockets than existed in entire libraries a generation ago. The constraint is not access to information but the ability to find relevant information, evaluate its quality, and synthesize it effectively.
Expertise is distributed, not concentrated: On any given topic, relevant expertise is distributed across thousands of specialists worldwide—academic researchers, practitioners, policy analysts, journalists, and experienced debaters who have studied the issue intensely. No single teacher possesses comprehensive knowledge, and trying to channel all learning through one instructor creates an artificial bottleneck.
Collaboration is frictionless, not difficult: Students can share information instantaneously through digital platforms, coordinate across time zones, access shared knowledge bases, and contribute to collective projects without physical proximity. The question is not whether they can collaborate but whether education is teaching them to do so effectively.
Knowledge evolves rapidly, not slowly: In many domains, the half-life of knowledge is shrinking. What students memorize today may be outdated in years or even months. What matters is not the facts currently in their heads but their ability to continuously update their understanding as new information emerges.
Debate operates in this world of information abundance:
Students don’t memorize evidence—they maintain searchable databases and learn to retrieve what they need during prep time. The skill is not “What do I remember?” but “How quickly can I find the evidence that answers this specific argument?”
Students don’t depend on a single teacher’s expertise—they draw from coaches, teammates, opponents, judges, online forums, and the accumulated wisdom of the community. The skill is not “What did my teacher tell me?” but “Who in my network has relevant knowledge, and how do I access it?”
Students don’t work in isolation—they coordinate through digital platforms, share resources freely, and contribute to collective knowledge bases. The skill is not “What can I do alone?” but “How can I leverage collective resources and add value to the system?”
Students don’t learn static content—they engage with issues that evolve in real-time as new evidence emerges, as opponents develop novel arguments, and as tournament results reveal what actually persuades judges. The skill is not “What did I learn at the start?” but “How quickly can I adapt to new information?”
This is education designed for information abundance. And it works.
Why the Giant Brain Model Produces Better Learning
The evidence that debate produces exceptional learning outcomes is overwhelming. Debaters develop critical thinking skills, content knowledge, communication abilities, and cognitive flexibility that far exceed what traditional education produces in equivalent time.
Why?
Because the giant brain model aligns with how humans actually learn best—and it creates conditions that traditional classrooms cannot replicate.
Learning through explaining and defending
Cognitive science research on the “generation effect” and “retrieval practice” shows that actively producing information (rather than passively receiving it) creates much stronger learning. When students must explain their arguments to judges, defend them against hostile cross-examination, and adapt them based on opponent challenges, they engage in the deepest form of active learning.
In traditional classes, students might hear a lecture on encryption policy, take notes, and answer some comprehension questions. In debate, students must:
Construct an encryption argument from evidence they’ve researched
Explain it clearly to a judge who may know nothing about cryptography
Answer aggressive questions from opponents trying to expose weaknesses
Respond when opponents present contrary evidence
Synthesize their position against three other arguments happening simultaneously
Do all of this under time pressure, without notes, while being evaluated
The cognitive demand is exponentially higher—and so is the learning.
Learning through failure and iteration
Debate creates what psychologists call a “desirable difficulty”—challenges that feel frustrating in the moment but produce deeper, more durable learning.
When a student runs an argument and loses, they receive immediate, specific feedback about what failed: “Your cybersecurity impact was too abstract—you needed concrete scenarios.” “Your opponent’s alternative investigation methods went unanswered.” “You won on magnitude but lost on probability, and you never explained why I should weigh magnitude over probability.”
Then they have another tournament the next weekend to apply that feedback. And another. And another.
This rapid iteration cycle—test, fail, analyze, adjust, retest—is precisely what produces expertise in every domain. Research on deliberate practice shows that improvement comes from repeatedly attempting tasks at the edge of current ability, receiving immediate feedback, and making targeted adjustments.
Traditional education rarely creates these conditions. Students might write an essay, receive feedback two weeks later, and never write on that topic again. There’s no iteration. No opportunity to immediately apply the critique. No testing whether the adjustment actually improved performance.
Debate’s tournament structure forces iteration. Students run similar arguments across multiple rounds and multiple weekends, refining based on what works and what fails. By the end of a topic, strong debaters have iterated on core arguments 20-30 times, incorporating feedback from dozens of judges, opponents, and coaches.
No traditional classroom assignment comes close to this level of repeated, refined practice.
Learning through distributed cognition
Research on collaborative learning shows that students learn more when they work together—but only under specific conditions. Ineffective group work involves one student doing most of the thinking while others passively observe. Effective group work involves complementary expertise, genuine interdependence, and accountability for individual contributions.
Debate creates optimal collaborative learning conditions:
Complementary expertise: Partners, teammates, and squads develop specialized knowledge that requires genuine coordination. One student cannot know everything about cryptography, constitutional law, criminology, and economics. The team must distribute cognitive labor and synthesize insights.
Genuine interdependence: Your success literally depends on others. If your partner doesn’t prepare responses to the cybersecurity argument, you both lose. If your squad doesn’t share evidence they found, you all have weaker cases. The incentives align toward genuine collaboration.
Individual accountability: Even within partnerships, each debater speaks individually. You cannot hide behind a partner’s knowledge. In cross-examination, you must defend your own claims. In rebuttals, you must synthesize arguments on your feet. The structure ensures that collaboration enhances rather than replaces individual development.
This distributed learning extends beyond immediate partners to the entire community. When strong teams post cases on OpenCaselist, everyone benefits. When judges provide thoughtful written feedback, the whole community learns. When tournaments bring together students from diverse schools and backgrounds, everyone is exposed to different perspectives and approaches.
The result is learning that scales. Instead of thirty students learning in isolation from one teacher, you have hundreds of students learning from each other, from dozens of coaches, from judges with diverse expertise, and from the accumulated wisdom of the community.
Learning through diversity of interaction
One of the most powerful but underappreciated aspects of debate is the sheer diversity of people students engage with.
In a typical school year, a student might interact academically with:
5-8 teachers
30-120 classmates from their school
Occasional guest speakers
In a typical debate season, a student interacts with:
3-6 coaches with different backgrounds (former debaters, attorneys, teachers, graduate students)
15-100+ squad members across different skill levels
50-100 opponents from different schools, regions, and backgrounds
50-75 judges with wildly varying expertise (former debaters, lawyers, academics, parents, community members)
Hundreds of students whose cases they read on OpenCaselist
Thousands of students whose tournament performances provide data about argument effectiveness
This diversity is pedagogically crucial. Research on “productive friction” in learning shows that encountering different perspectives, approaches, and standards forces deeper thinking than operating within a homogeneous environment.
When a student must explain encryption policy to:
A parent judge with no technical background
A former debater who values precise evidence comparison
An attorney who focuses on constitutional analysis
A computer science professor who expects technical accuracy
...they develop communication flexibility that goes far beyond what any single classroom provides.
When a student competes against:
A well-funded private school team with extensive resources
A small-town public school team with creative arguments
An urban debate league team with different strategic priorities
A homeschool team with unusual research focuses
...they encounter intellectual diversity that challenges assumptions and expands their strategic thinking.
This is preparation for a pluralistic world where professional success depends on communicating across expertise gaps, collaborating across cultural differences, and synthesizing perspectives from diverse stakeholders.
The Future of Work Is Already Here in Debate
Futurists and labor economists describe the emerging workplace as:
Network-based rather than hierarchical: Knowledge flows through horizontal networks, not just top-down authority
Project-based rather than role-based: People assemble into temporary teams with complementary expertise rather than working in fixed organizational silos
Collaborative rather than individualistic: Value creation comes from coordinating distributed expertise, not individual genius
Adaptive rather than stable: Rapid technological and market changes require continuous learning and strategic adjustment
Digitally mediated: Most professional collaboration happens through digital platforms that enable asynchronous coordination and knowledge sharing
Every single one of these characteristics describes how competitive debate already operates.
Debate is network-based: Knowledge flows through partnerships, squads, and the broader community. Hierarchy exists (more experienced debaters and coaches provide guidance), but learning happens primarily through horizontal exchange—teammates sharing evidence, opponents testing arguments, peers posting cases online.
Debate is project-based: Teams assemble different configurations of expertise for each topic. The student who specialized in economic research for the last topic might focus on legal analysis for the current one. Partnerships sometimes change. Squads reorganize based on who’s available and what the strategic needs are.
Debate is collaborative: No individual succeeds alone. Even the strongest debater needs a partner, teammates, coaches, and access to community resources. Value comes from coordinating distributed expertise—your evidence, your partner’s strategic insight, your coach’s experience, your squad’s collective research.
Debate is adaptive: Every tournament provides new information about what arguments work, what strategies opponents are running, and what judges find persuasive. Teams that cannot rapidly adapt based on this feedback fall behind. The meta evolves continuously, requiring constant strategic adjustment.
Debate is digitally mediated: Evidence databases, case lists, group chats, Discord servers, online forums, and video recordings of elimination rounds create a digital infrastructure for knowledge sharing and coordination. Students who cannot effectively navigate these platforms are at a severe disadvantage.
In other words, debate is not preparing students for a future workplace. It is immersing them in a present reality that traditional education pretends doesn’t exist.
The Pedagogical Superiority of the Giant Brain Model
When we compare the traditional isolated-desk model to the distributed-intelligence model, the pedagogical advantages are stark:
The traditional model made sense when knowledge was scarce, experts were rare, and collaboration was difficult. The giant brain model makes sense now, when knowledge is abundant, expertise is distributed, and collaboration is frictionless.
Learning to Think Like a Network
Perhaps the deepest lesson debate teaches is epistemological: how to think like a network rather than like an isolated individual.
When students first enter debate, they often approach arguments with an individualistic mindset: “This is my case. These are my ideas. I need to defend them against attack.”
By the end of their first season, effective debaters have internalized a network mindset: “This argument came from evidence I found, synthesis my coach suggested, strategic framing I learned from watching elimination rounds online, and refinements based on feedback from three tournaments. My opponents will test it. If it fails, I’ll incorporate their critiques and improve it. If it succeeds, I’ll share it with my squad and the broader community through OpenCaselist.”
This shift—from “my thinking” to “our collective thinking”—represents genuine cognitive development. It’s not abandoning individual agency. It’s recognizing that individual thinking is always embedded in social and informational contexts, and that acknowledging this explicitly makes you a better thinker.
All knowledge is recombinant. All thinking is distributed. All innovation emerges from networks.
The question is not whether students will need to function as nodes in collective intelligence systems. They will. The question is whether education is teaching them to do so effectively.
Traditional education pretends students are isolated minds who should develop knowledge independently. Then it expresses surprise when graduates cannot collaborate effectively, synthesize across disciplines, adapt to rapid change, or contribute to organizational intelligence.
Debate skips the pretense. It throws students into a distributed intelligence system from day one and teaches them to thrive within it. The result is not students who cannot think for themselves. It’s students who understand that “thinking for yourself” actually means thinking effectively within networks of collective intelligence—leveraging distributed expertise, testing claims through adversarial engagement, iterating based on feedback, and contributing insights that benefit others.
That is the future of knowledge work. That is the reality of how learning, thinking, and contributing actually operate in every sophisticated domain.
Debate has been training students to do it for decades.
The isolated desk was always a fiction. The giant brain is reality. Education should catch up.
How Debate’s Giant Brain Mirrors AI Development
Multi-Agent Collaboration with Millions Interacting
In Debate: The debate community functions as a distributed intelligence network where thousands of debaters, coaches, and judges simultaneously explore the same problem space. Each tournament creates hundreds of parallel experiments testing different arguments, with results aggregated through competitive outcomes. Knowledge propagates through the network—when one team discovers effective evidence or framing, it spreads via OpenCaselist, squad sharing, and direct observation. Weak arguments get eliminated quickly; strong ones proliferate and improve through iteration.
In AI: Modern AI systems increasingly learn through multi-agent interaction. Instead of training a single model in isolation, researchers now deploy millions of AI agents that interact with each other, with humans, and with diverse environments. Each interaction generates training data. Systems like AlphaGo Zero learned by playing millions of games against copies of themselves—no human games required. Large language models are now trained not just on static human text but on synthetic data generated by other AIs, interactions with users across millions of conversations, and outputs from other models.
The Parallel: Both systems achieve intelligence through massive parallelization. You can’t make one debater 1000x smarter, but you can have 1000 debaters explore different approaches simultaneously and aggregate the results. Similarly, you can’t make one AI think 1000x longer on a problem with guaranteed improvement, but you can run 1000 AI agents exploring different solution paths and combine their insights. The intelligence emerges from the system, not from any individual node operating in isolation.
Training on Other Agents’ Outputs (Meta Training with Chinese Models)
In Debate: Debaters don’t just learn from original sources—they extensively learn from what other debaters have already produced. They read cases on OpenCaselist (outputs from other teams), adopt argument structures that worked for others, build on evidence compilations from brief companies, and iterate on frameworks developed by previous generations. A novice team might start with a case structure pioneered by a national circuit team, then refine it based on feedback. The community’s knowledge compounds because each generation builds on previous outputs rather than starting from scratch.
In AI: This is now explicit in AI development. Meta’s recent approach involves training their models not just on human-generated data but on outputs from other AI systems—including Chinese models like DeepSeek. When GPT-5.2 trains on conversations that include Claude’s responses, or when new models train on synthetic data generated by previous models, they’re learning from other agents’ reasoning patterns, not just from original human sources. This “model-on-model” training creates a compounding effect where each generation of AI builds on the collective intelligence of previous generations.
The Parallel: Both systems recognize that intelligence is recombinant. Original human knowledge is the seed, but the real acceleration comes from agents learning from other agents’ processing of that knowledge. A debater learning from another team’s case isn’t “cheating”—they’re accessing a refined synthesis that represents hundreds of hours of research, testing, and iteration. Similarly, an AI learning from another AI’s outputs isn’t copying—it’s accessing distilled patterns that represent massive computational processing of original data. The distinction between “original” and “derivative” knowledge breaks down because all advanced cognition is fundamentally derivative and recombinant.
Chain-of-Thought: Iterative Reasoning
What Chain-of-Thought Is: Chain-of-thought (CoT) is a technique where AI systems are prompted to “show their work”—to externalize step-by-step reasoning rather than jumping directly to conclusions. Instead of:
Question: “What is 347 × 892?”
Answer: “309,524”
You get:
Question: “What is 347 × 892?”
Reasoning: “Let me break this down. 347 × 800 = 277,600. Then 347 × 90 = 31,230. Then 347 × 2 = 694. Adding those: 277,600 + 31,230 + 694 = 309,524.”
Answer: “309,524”
The model explicitly works through intermediate steps, which dramatically improves accuracy on complex reasoning tasks. Even more powerful is when AI systems iterate on their own reasoning—generating an answer, evaluating it, refining their approach, and trying again.
In Debate: This is structurally identical to how debate works. Debaters don’t just assert conclusions—they must externalize their reasoning chain:
Claim: “Encryption backdoors increase cybersecurity risks”
Warrant chain: “Any backdoor mechanism is a potential vulnerability → Historical cases prove backdoors get exploited (Greek surveillance, Juniper Networks) → Exploitation causes massive damage (WannaCry: $4B) → Therefore backdoors create unacceptable systemic risk”
Then opponents stress-test each link in the chain. If the warrant “backdoors always get exploited” fails (maybe some backdoor systems haven’t been compromised), the debater must iterate—refining the claim to “backdoors create high probability of exploitation” and adding evidence about mathematical impossibility of perfectly secure backdoors.
The tournament cycle creates iterative reasoning at scale:
Initial reasoning (pre-tournament prep)
Testing (rounds expose flawed links)
Evaluation (judge feedback identifies which step failed)
Refinement (between-round prep patches the weak link)
Re-testing (next round validates the improvement)
Meta-iteration (across tournaments, argument chains become increasingly robust)
In AI: Modern AI systems now use similar iterative reasoning. Systems like OpenAI’s o1 don’t just generate one answer—they:
Generate initial reasoning chain
Evaluate it for logical consistency
Identify weak steps
Generate alternative reasoning paths
Compare approaches
Synthesize the strongest reasoning chain
Produce final answer
Some systems even use “self-consistency” checking—generating multiple reasoning chains and seeing if they converge on the same answer, similar to how debate tests arguments across multiple judges and rounds.
The Parallel: Both systems achieve reliability through externalized, testable reasoning chains rather than opaque intuition. A debater who just asserts “backdoors are bad” without showing their reasoning loses to opponents who can attack unstated assumptions. An AI that jumps to conclusions without showing intermediate steps fails on complex problems where any single reasoning step might be wrong.
The iterative refinement is crucial in both cases. Debate’s tournament structure forces continuous iteration—you can’t just “think harder” in isolation; you must test your reasoning against adversaries, receive feedback, and refine. Similarly, AI systems that iterate on their reasoning (through techniques like self-refinement, debate between multiple model instances, or process reward models) dramatically outperform single-pass reasoning.
The Deeper Insight
What’s remarkable is that the same architectural principles that make debate effective for human learning are now being deliberately engineered into AI systems:
Distributed exploration over individual optimization (multi-agent > single genius)
Learning from processed outputs, not just raw sources (model-on-model training = debaters learning from cases)
Externalized, iterative reasoning chains (CoT = flowing arguments across speeches and tournaments)
Adversarial testing (AI debate models, red-teaming = competitive rounds)
Selection pressure on outputs (reinforcement learning from feedback = tournament results eliminating weak arguments)
Debate didn’t just accidentally stumble onto an effective pedagogy. It discovered fundamental principles of how collective intelligence systems learn and improve—principles that now form the cutting edge of AI development.
The students learning to function as nodes in the debate giant brain aren’t just preparing for future workplaces. They’re learning the exact cognitive architecture that increasingly powers the most sophisticated artificial intelligence systems humanity is building.
What AI Actually Changes (and What It Doesn’t)
So where does AI fit into this system?
AI tools like ChatGPT, Claude, and specialized debate research assistants can help students brainstorm arguments, find evidence more quickly, draft case outlines, and generate initial responses to common objections. This worries critics because it seems to bypass the hard cognitive work of developing arguments from scratch.
But this concern rests on the same myth of solitary originality that debate has always rejected.
Excellent point. Let me expand on how AI itself becomes part of the giant brain’s distributed cognitive system, not a replacement for it:
AI as a Node in the Distributed Network
The giant brain framework helps us understand that AI doesn’t replace the debate network—it becomes another participant in it. Just as a brief company or coaching staff contributes knowledge that gets refined through the community’s adversarial testing, AI contributes hypotheses and frameworks that enter the same validation process.
Consider what happens when AI-generated arguments enter the debate ecosystem:
Week 1: ChatGPT suggests a novel framing—that encryption backdoors should be analyzed through “security by obscurity” principles from cybersecurity theory. A few teams try this argument.
Week 2: Opponents test it. Some judges find it persuasive. Others point out that “security by obscurity” traditionally refers to keeping security mechanisms secret, not creating intentional access points. The argument gets refined.
Week 3: Teams research the actual cybersecurity literature on “security by obscurity” to defend against this objection. They discover Kerckhoffs’s principle and Shannon’s maxim. The argument evolves: it’s not about obscurity, but about the cryptographic principle that systems should be secure even when the adversary knows the system design—which backdoors violate.
Week 4: This refined version spreads through the network. New teams use it. New opponents test it against different frameworks. It continues evolving.
AI contributed the initial framework. But the giant brain refined it through iterative testing across hundreds of rounds with thousands of participants.
Iterative Testing Across the Network
This is where the giant brain’s distributed architecture provides something AI alone cannot: simultaneous testing across diverse contexts.
When AI generates an argument, it draws on patterns in its training data. But it cannot:
Test the argument against a parent judge with no technical background vs. a former debater who competed on encryption topics
Discover how the argument performs when opponents have superior evidence quality vs. superior strategic framing
Learn which impact scenarios resonate emotionally vs. which seem abstract and unconvincing
Identify which technical explanations clarify vs. which confuse non-expert audiences
The debate network conducts these tests in parallel. Every weekend, hundreds of rounds simultaneously stress-test arguments across:
Different judge philosophies (tech, lay, flow, truth-testing)
Different opponent strategies (impact turn, counterplan, kritik, defensive case)
Different evidence qualities (peer-reviewed studies vs. think tank reports vs. news articles)
Different time constraints (tight rounds vs. rounds with extra prep)
Different contexts (local tournaments vs. national circuits, novice vs. varsity)
This produces ecological validity that no AI training process can replicate. The giant brain learns what actually works in practice, not what should theoretically work.
Knowledge Integration Through Collective Memory
AI has vast knowledge, but that knowledge remains latent until activated by specific queries. The debate community creates institutional memory that integrates AI-generated insights into a living, evolving knowledge base.
Here’s how this works:
AI generates: A sophisticated argument about warrant requirements violating international mutual legal assistance treaties (MLATs).
The network tests and refines:
Team A tries it, discovers opponents have strong “domestic policy focus” responses
Team B develops MLAT-specific evidence about investigation delays
Team C finds the argument works better on certain topics (counterterrorism) than others (organized crime)
Team D creates a hybrid approach that front-loads domestic arguments but extends to MLATs in later speeches
The network integrates:
Successful versions get included in case sharing
Tournament champions identify their approach in round reports
Coaches discuss strategic deployment at workshops
The refined argument becomes part of community knowledge
AI learns from this: When the next student queries about encryption warrants, if AI has access to updated debate literature, it now suggests the refined version the community developed—not just the initial hypothesis.
This creates a feedback loop where:
AI contributes knowledge
The giant brain tests it adversarially
Successful refinements become part of shared knowledge
AI’s future outputs improve based on what the community validated
Why the Human Network Still Matters
The critical insight is that AI has knowledge, but the debate community has validation.
AI can tell you:
“Encryption backdoors create vulnerabilities”
“Fourth Amendment protections may apply to digital communications”
“Critical infrastructure risks include power grids and financial systems”
But only the debate network can tell you:
Which vulnerability evidence survives technical cross-examination
Which Fourth Amendment framing resonates with parent judges vs. flow judges
Whether “critical infrastructure” impacts outweigh “child exploitation” impacts when both sides have strong evidence
How to adapt the argument when opponents introduce the “going dark” problem
Which explanation analogies actually help lay judges understand complex cryptography
This is procedural knowledge—knowledge about how to use knowledge effectively in specific contexts. AI can help generate it through simulation, but the debate network validates it through real adversarial pressure with actual stakes.
The Giant Brain Improves AI, Not Just Vice Versa
Here’s where the framework gets really interesting: the debate community’s collective intelligence can actually improve AI outputs.
When thousands of debaters iteratively test AI-generated arguments:
They identify which frameworks are logically sound but strategically weak
They discover empirical claims that seem plausible but collapse under scrutiny
They find which analogies and explanations actually clarify complex issues
They learn which impact scenarios are compelling vs. which seem contrived
This collective learning becomes:
Training data for future AI models
Corrections to AI-generated misconceptions
Refinements to AI-suggested strategic approaches
Context that helps AI understand what matters in practice vs. what sounds good in theory
The giant brain, in other words, teaches AI what works through distributed experimentation that no individual researcher or AI training process could efficiently replicate.
1. It positions debate and AI as complementary rather than competitive: AI contributes hypotheses; debate validates them. Together they create a more powerful cognitive system than either alone.
2. It explains why debate remains valuable even as AI improves: The better AI gets at generating arguments, the more valuable debate’s adversarial testing becomes for determining which AI-generated arguments actually work.
3. It demonstrates unique educational value: Students learn to be critical consumers of AI-generated knowledge by participating in the distributed validation process. This is exactly the skill they need for an AI-dominated future.
4. It answers the “why not just use AI?” question definitively: Because AI provides hypotheses, but the giant brain provides validated, context-specific, battle-tested knowledge that AI cannot generate alone.
The debate community isn’t being replaced by AI. It’s becoming the quality control system that determines which AI-generated knowledge is actually reliable, useful, and persuasive in practice.
Why the Giant Brain Matters
Understanding debate as a distributed cognitive system reframes the entire conversation about originality and AI.
The goal of education is not to produce students who reinvent knowledge from scratch in isolation. The goal is to produce students who can think critically, evaluate evidence, construct coherent arguments, recognize weak reasoning, adapt to new information, and make sound judgments under pressure. Those capacities develop through engagement with shared knowledge, not rejection of it.
Debate trains those skills more effectively than most educational interventions precisely because it makes knowledge social, iterative, and competitive. Students learn by arguing with each other, borrowing the best ideas, testing them publicly, and refining them based on what works.
The giant brain accelerates learning because it harnesses collective intelligence. Better arguments rise not because a single genius invented them but because thousands of students tested variations, judges rewarded stronger reasoning, and the community iterated toward clarity.